Nvidia Bets Its AI Moat Is the Whole Rack, Not Just the GPU
techcrunch.com · Publisher photograph, editorial use approved
The Core · TL;DR
- Nvidia's August 27 earnings framed its AI advantage as spanning the full rack, not just the GPU, ahead of its Vera Rubin architecture rollout.
- Vera Rubin pairs the Rubin GPU with Nvidia's Vera CPU, a Groq 3 LPX inference accelerator, and matched storage/networking racks.
- Nvidia reports up to 3x improvement in workloads accelerated by the Vera CPU, easing flash storage bottlenecks.
- The shift comes as rivals like OpenAI build custom silicon (Jalapeño) aimed at cutting data movement, and after Nvidia's market cap grew 10x from 2023 to mid-2025.
Nvidia used its August 27 earnings call to reframe what makes its AI hardware hard to copy. The pitch was no longer just about GPU horsepower, but about the entire rack around it: CPUs, networking, storage and inference chips designed to move as one system.
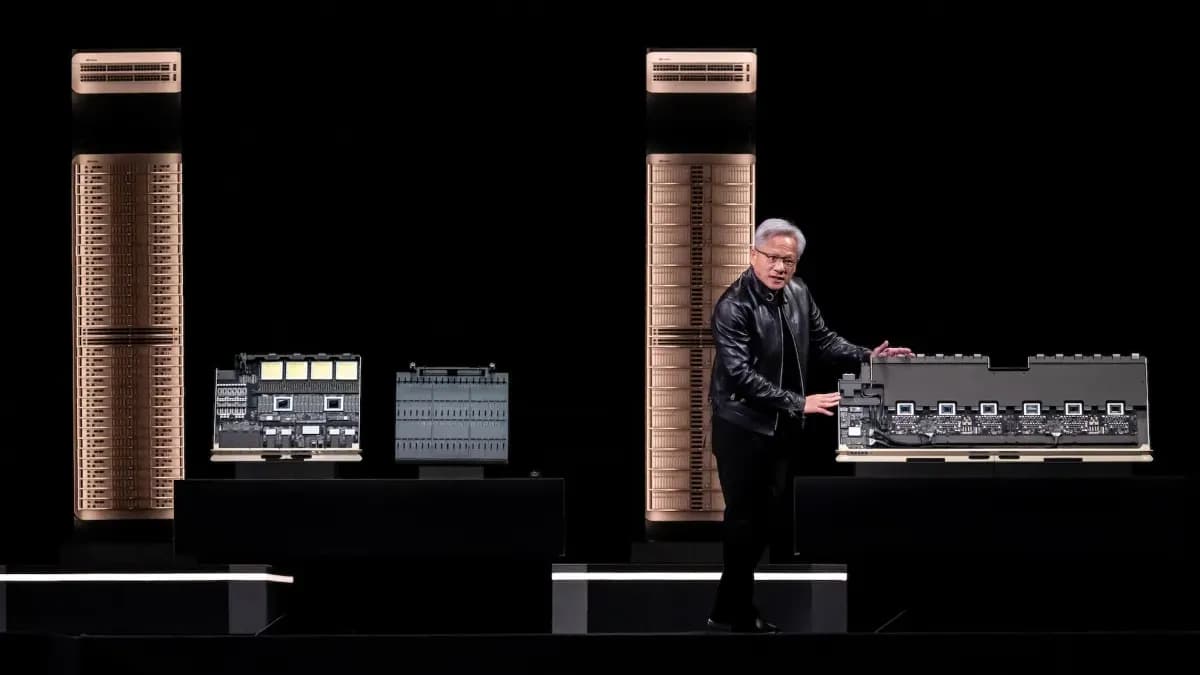
That message arrives alongside the company's next architecture, Vera Rubin, which pairs the Rubin GPU with Nvidia's own Vera CPU, a Groq 3 LPX inference accelerator, and matching storage and networking racks built to work together rather than as separate parts bolted onto a server.
The core problem Nvidia says it is solving is data movement, not raw compute. As AI clusters scale into gigawatts of power draw, keeping thousands of chips fed with data without idling becomes its own engineering challenge, and orchestration across the whole rack matters as much as any single chip's speed.
Nvidia's numbers back up the emphasis on system-level design. The company reported up to a 3x improvement in workloads where the Vera CPU handles acceleration tasks, letting flash storage run at closer to its full potential instead of being throttled by slower data pipelines elsewhere in the system.
Why the full-stack pitch matters now
The timing is not incidental. Nvidia's market capitalization grew roughly tenfold between early 2023 and mid-2025, a run built almost entirely on GPU demand for AI training and inference.
That growth has also drawn competitors who no longer just want a faster GPU alternative. OpenAI, for instance, has been developing its own chip, Jalapeño, built specifically to cut down on the amount of data that needs to shuttle between components during inference.
That approach targets precisely the bottleneck Nvidia is now positioning Vera Rubin to solve. If chipmakers and AI labs increasingly compete on system-level efficiency rather than transistor count alone, Nvidia's push to control CPU, GPU, networking and storage design simultaneously looks less like product-line expansion and more like a defensive perimeter around its core GPU business.
Whether that full-stack bundling holds up against custom silicon from OpenAI and other well-funded labs building their own inference chips will likely shape the next phase of the AI hardware race more than any single benchmark number Nvidia publishes this quarter.
Original reporting and research used to synthesize this article.
WAKIB Editorial Team
This review was prepared and summarized by the WAKIB AI intelligence engine and vetted by our editorial board for accuracy and reliability.
Subscribe to Newsletter
Get a weekly summary of the most promising AI research and tools delivered to your inbox.
Telegram Channel
Join our active community on Telegram for real-time tracking of AI models and trends.